Hub · Delhi
Delhi AI Alignment and Safety Collective
The science of how intelligence goes wrong.
Arunachal Pradesh Assam Chandigarh Karnataka Manipur Meghalaya Mizoram Nagaland Punjab Rajasthan Sikkim Tripura Uttarakhand Telangana Bihar Kerala Madhya Pradesh Andaman & Nicobar Gujarat Lakshadweep Odisha Dadra and Nagar Haveli and Daman and Diu Jammu & Kashmir Chhattisgarh Delhi Goa Haryana Himachal Pradesh Jharkhand Tamil Nadu Uttar Pradesh West Bengal Andhra Pradesh Puducherry Maharashtra Ladakh AI Safety NITA Agartala Delhi AI Safety India Bengaluru Bengaluru Boundaries traced from Survey of India maps by DataMeet (CC BY 4.0). Not to scale.
Weekly Discussions on alignment and misalignment Any field Curiosity about foundations is enough Online And in person in Delhi 4 areas Of research, intelligence dynamics first
Now and next
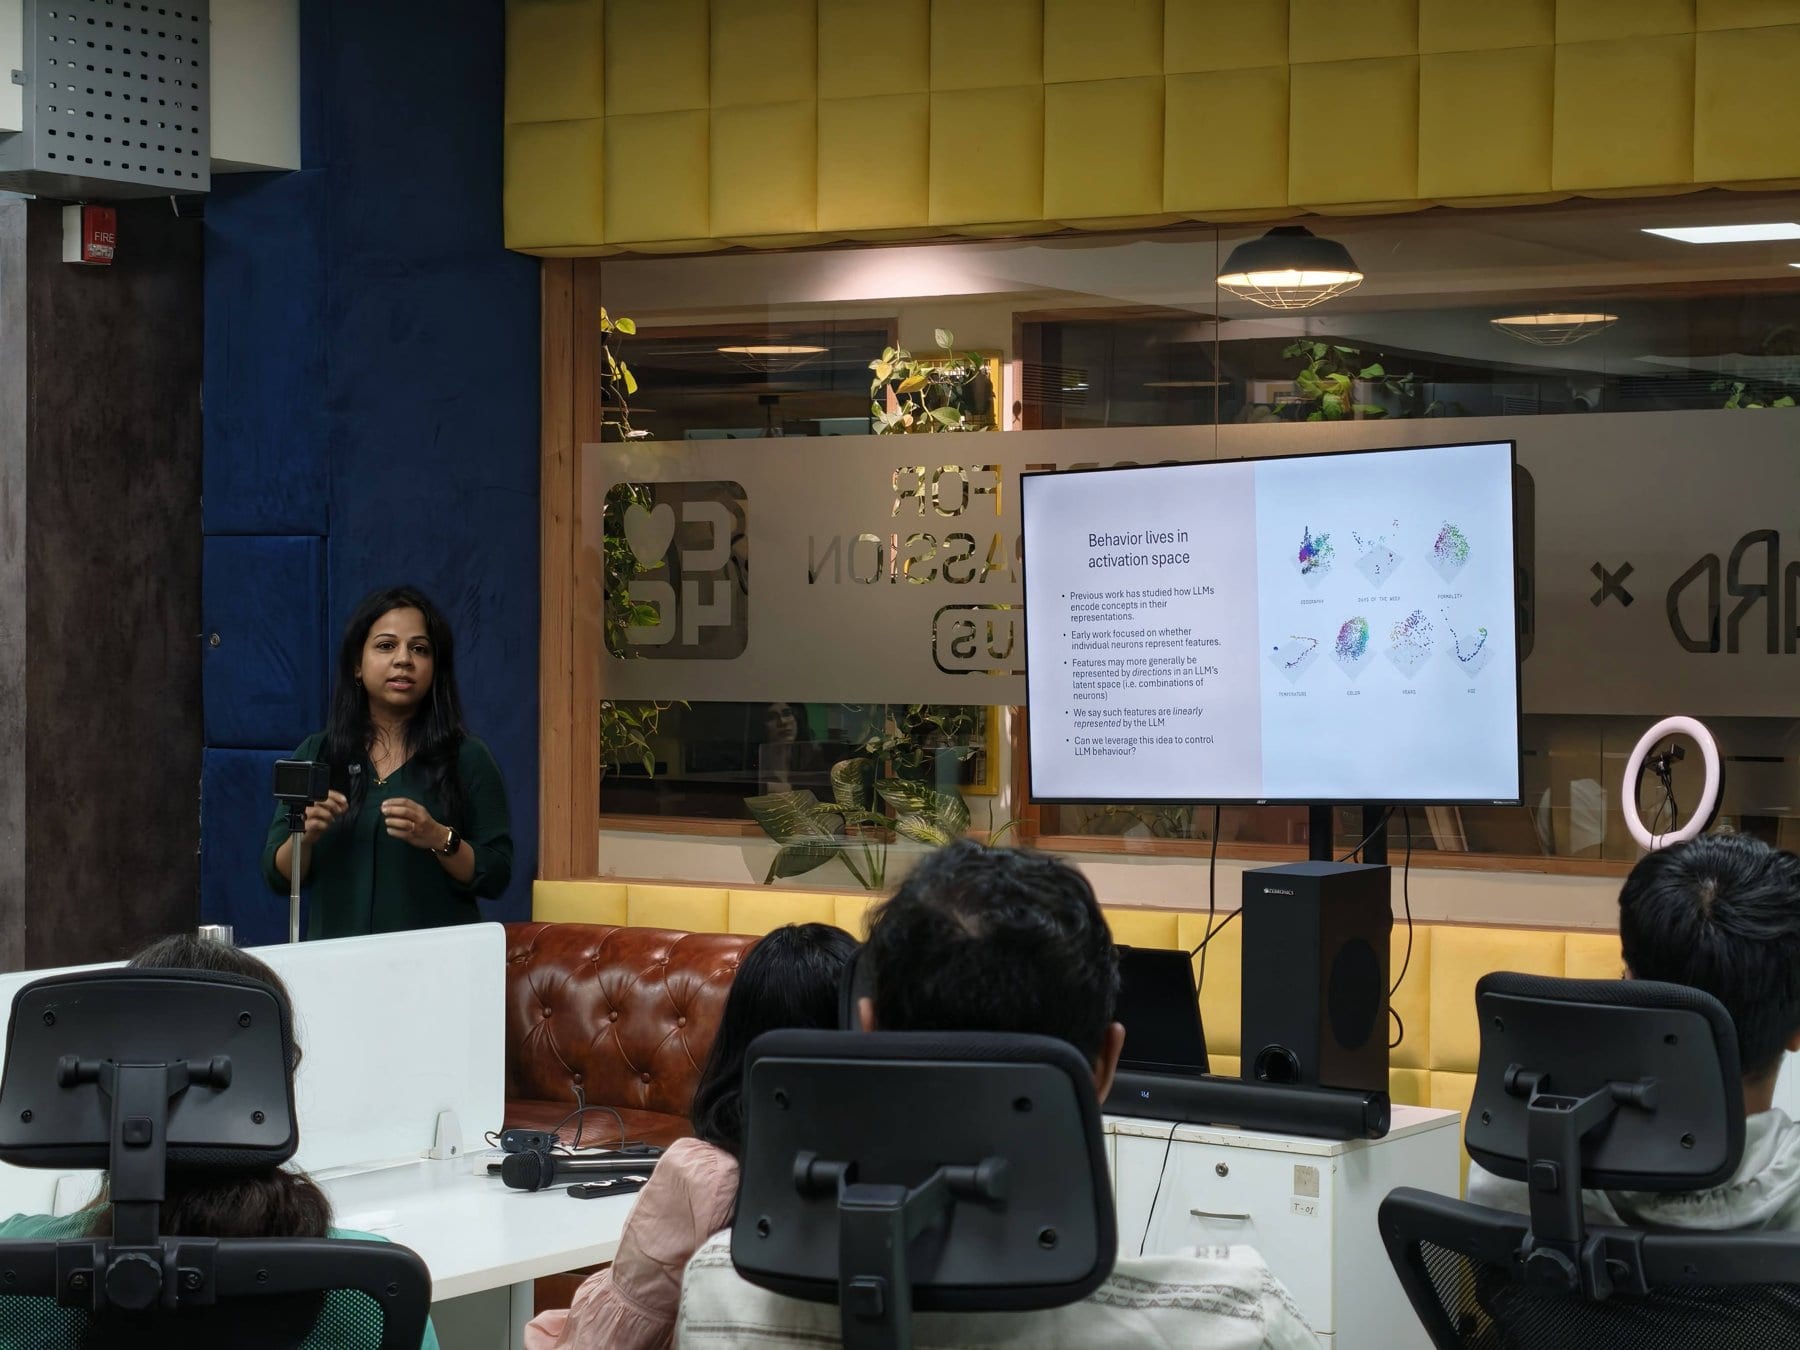
Weekly discussion group Structured discussions on alignment, misalignment and intelligence dynamics. Beginner-friendly and open to all.
Active now Research working group Members move into active research, with real output: papers, preprints and policy memos.
Late 2026
Research focus Alignment as a consequence of how intelligence works, not a patch.
Intelligence dynamics and misalignment Multi-agent systems Alignment and control Foundations of intelligence
Who it’s for
Researchers in AI and ML You work on safety-adjacent problems and want rigorous theoretical grounding.
Scientists from adjacent fields Cognition, complex systems, neuroscience. The problems here are interdisciplinary.
Students CS, ECE, cognitive science. Any year, any university.
Mentors Active in technical alignment or complex systems research.
Meetups in Delhi In person, from our Luma calendar.
Understand how intelligence goes wrong, not just patch it.
Who runs it A field-building initiative with the AI Safety India community.
Collective organiser Rishika Rai Researching the science of scheming through dynamical systems and multi-agent modelling.
About Rishika Built a computational model of emotional neuroplasticity using neural networks: a state-space formulation of how adaptive cognitive systems reorganise under affective and attentional dynamics (Brainstorm: A Neuroscience Challenge, Devpost 2025).
Currently researching the science of scheming through dynamical systems and resilience engineering, with a focus on emergence, attractor formation and modelling multi-agent systems.
MSc, Computer Science (Machine Learning and AI), Woolf University
With the support of
Research focus Intelligence dynamics and misalignment How behaviour emerges, stabilises and fails across intelligent systems: attractor formation, scheming detection in model organisms, and deceptive alignment.
We treat alignment and safety as parts of a broader problem, not endpoints. The usual frame: a system produces bad output, so fix the output. Ours: understand what makes intelligence coherent, controllable and stable.
Research focus Multi-agent systems Coordination failures and unsafe emergent behaviour in networks of AI agents.
Research focus Alignment and control Scalable oversight, control evaluations and deceptive alignment, studied as structural properties, not output constraints.
Research focus Foundations of intelligence Physics-like invariants and constraints in intelligent systems, and how new abstractions emerge from them.
Join the Collective Bring your questions to the next discussion.
About you Two short steps, about 3 minutes in all.
Continue
What you are looking for Pick what feels most true right now. You can change direction later.
Join the group Back
Welcome, there . A confirmation is on its way to your email .
01 We read it A hub organiser reads every request. 02 You get the next invite For the next session, by email. 03 You join the reading Online or in person. Reference